Business, Deals & Funding
Ars Technica AI
Microsoft disrupts AI-assisted platform that compromised 12,000 accounts
Microsoft led an industry-wide disruption of EvilTokens, a subscription-based cybercrime platform ($1,500 initial fee plus $500/month) that used an AI chatbot to compromise 12,000 Microsoft accounts across 10,000 organizations worldwide. The platform automated mass phishing via abuse of OAuth device code authentication flows, then used AI to analyze victim inboxes, identify high-value targets, map trusted relationships, and draft convincing follow-up emails for business email compromise (BEC) fraud. Microsoft seized 50 websites and 150 domains, while UK police arrested two suspects. The platform exploited Microsoft Entra's device code login process, using Node.js backend logic to generate dynamic device codes and evade signature-based detection. Victims spanned industries including financial services, healthcare, construction, and higher education, with the US being the most affected co…
Why it matters
This case illustrates a concerning but predictable evolution in cybercrime: the productization of AI-assisted attack platforms that dramatically lower the skill barrier and time-to-compromise for business email compromise schemes. The use of legitimate OAuth device code flows is particularly notable — it's a clever abuse of a real authentication mechanism designed for constrained devices, which makes it harder to detect than traditional credential phishing. The subscription pricing model ($1,50…
Claude Code Changelog
v2.1.280
Version 2.1.280 of Claude Code adds Claude Opus 5.5 as the new default Opus model with 1M context and updated pricing ($4/$20 per Mtok, $0.20/Mtok cache reads). It also introduces mouse support for more fullscreen lists (skills list scrolling and plugin state options), a new CLAUDE_CODE_MAX_MCP_DESCRIPTION_LENGTH environment variable to customize the 2,048-character cap on MCP tool descriptions and server instructions, and improvements to hook output size reporting including counts of oversized outputs.
Why it matters
This is a solid incremental release. The headline feature is the Opus 5.5 upgrade with its 1M context window, which is a significant capability boost for users working with large codebases. The MCP description length configuration is a welcome quality-of-life improvement for power users who found the 2,048-character cap restrictive for complex tool definitions. The mouse support additions and hook output reporting are nice polish items that show continued attention to the interactive experience…
Guardian AI
Trump praises Burnham despite tensions over AI, Chagos Islands and Iran
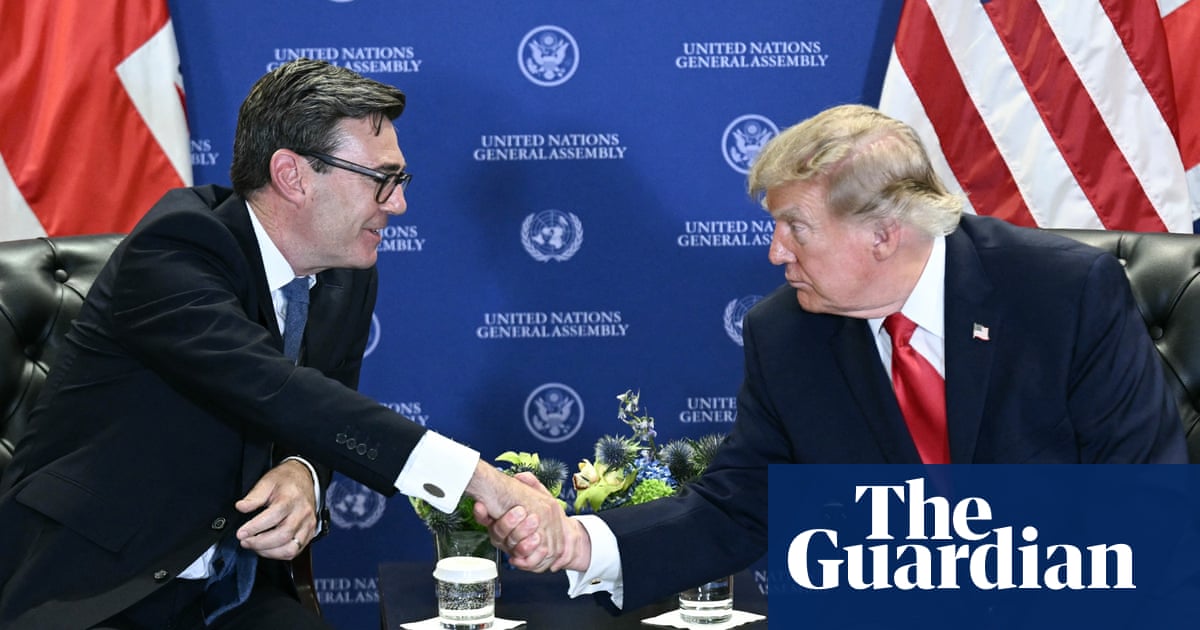
Donald Trump praised UK Prime Minister Andy Burnham as a 'natural businessperson' during their first face-to-face meeting at the UN General Assembly in New York, claiming relations with the UK are better under Burnham than they were under his predecessor Keir Starmer. However, tensions remain between the two countries on several issues including AI regulation, the Chagos Islands, and the war in Iran.
Why it matters
This article highlights the complex and often performative nature of diplomatic relationships. Trump's public praise of Burnham, while notable, should be viewed in the context of his well-documented tendency to use flattery as a negotiating tactic. The substantive policy disagreements on AI regulation, the Chagos Islands, and Iran suggest that the underlying relationship between the US and UK remains strained on key issues regardless of personal rapport between leaders. The real test of this re…
Lenny's Newsletter
Opus 5.5 vs. GPT-6 Sol: which model won my blind taste test?
Claire Vo ran a blind taste test comparing Opus 5.5, GPT-6 Sol, GPT-6 Astra, and other models across writing, frontend prototypes, long-running agentic tasks, SVGs, coding, and video editing. She scored outputs without knowing which model produced them. Astra won her heart for creative tasks, Opus 5.5 emerged as the overall strongest especially for long-running agents and B2B frontend work, and Sol impressed on clear writing, readable PRDs, and price. She also ran a '3D Barbie Bench' fashion-game test that reminded her how far models still have to go. An LLM judge disagreed with her rankings, rewarding different qualities than she valued. The hands in the 3D results were described as 'tragic.'
Why it matters
This is a useful format for model comparison — blind evaluation with real work tasks rather than synthetic benchmarks — though the results are inherently subjective and reflect one person's workflow priorities. The finding that different models excel at different task types (Opus 5.5 for agentic/engineering work, Sol for writing clarity, Astra for creative output) aligns with what many practitioners observe and is more actionable than a single ranking. The LLM-judge disagreement is an interesti…
MIT Tech Review AI

Roundtables: The Deadly Failures of The Virtual Border Wall
MIT Technology Review reports that the US has spent billions over 25 years building a 'virtual wall' of surveillance towers along its southern border, but an investigation documented over a thousand people who moved through surveilled areas without being reached or apprehended and ultimately died there, including under newly installed AI-powered towers designed to automatically spot people, revealing repeated failures of the system's basic security and humanitarian promises.
Why it matters
This investigation highlights a critical tension in surveillance technology deployment: massive spending on detection systems means little without adequate response infrastructure. The finding that even AI-powered towers failed to prevent deaths suggests the problem isn't purely technological but systemic—detection without timely human intervention in vast, harsh terrain renders the surveillance investment largely ineffective at its stated life-saving goal. It raises important questions about w…
OpenAI
Better prompt caching for GPT-6
OpenAI announced improvements to prompt caching for their GPT-6 model family. Key changes include: higher default cache hit rates with discounts for shared prefixes reused within a 30-minute window (up to 90% discount on cached input tokens), a new Prompt Caching Dashboard for monitoring cache performance, a diagnostics tool to identify causes of cache misses, explicit cache breakpoints for choosing which prefixes to reuse, the ability to adjust reasoning effort without breaking cache, guidance on preserving cache when tools and instructions change, and cache prewarming to reduce latency for known context.
Why it matters
This is a solid infrastructure improvement from OpenAI focused on cost and latency optimization for agentic workloads. The diagnostics tooling and dashboard are particularly useful additions — prompt caching has historically been a black box for developers, so giving visibility into why cache misses occur is a meaningful step forward. The ability to change reasoning effort without breaking cache is a clever design choice that acknowledges how real agent loops work. The 30-minute cache window is…
Science Daily

MIT’s tiny flying robot gets 450% faster with AI
MIT researchers developed an AI-based control system that dramatically improves the speed and agility of their insect-scale flying robot. The two-part controller increased the robot's speed by about 450 percent and acceleration by about 250 percent compared to previous results, enabling it to perform 10 consecutive somersaults in 11 seconds even under wind disturbances. The robot, about the size of a microcassette and lighter than a paperclip, uses soft artificial muscles to drive its flapping wings. The key advance was replacing a manually-tuned controller with an AI-based system that balances performance with computational efficiency, achieving flight performance comparable to actual insects in terms of speed, acceleration, and pitching angle. The technology is aimed at enabling miniature robots to navigate confined spaces like earthquake rubble where conventional drones cannot operat…
Why it matters
This is a genuinely impressive engineering achievement that addresses one of the core challenges in micro-robotics: the gap between mechanical capability and control sophistication. For years, the hardware of these tiny flyers has outpaced the software directing them, and using AI to close that gap is a smart approach. The practical applications in search-and-rescue are compelling, though significant hurdles remain before deployment in real disaster scenarios — autonomous navigation, onboard se…
TechCrunch AI

‘We’re already fighting yesterday’s battle’: Greece’s prime minister gets candid about AI
Greek Prime Minister Kyriakos Mitsotakis visited San Francisco on a trade mission to promote Greece as a tech destination, but unusually for a head of state, he openly admitted that no government is prepared for AI's impact. Speaking at an Endeavor Greece event, he pitched Greece's economic recovery — noting the country borrows more cheaply than the U.S. and is set to regain developed market status from MSCI next year. He highlighted investments in digital infrastructure including a new HPE-built supercomputer, reformed stock option taxation, loosened labor laws, and tax incentives for returning Greeks. However, he was notably candid about AI challenges, saying governments are 'fighting yesterday's battle' and acknowledging he lacks answers to many AI policy questions that world leaders are privately debating. The visit included tours of Tesla and Sequoia Capital before heading to the U…
Why it matters
Mitsotakis's candor is refreshing and strategically smart. Most politicians either overpromise on AI regulation or avoid the topic entirely, so publicly admitting uncertainty signals intellectual honesty that resonates with a Silicon Valley audience. Greece's economic turnaround story is genuinely impressive — from 40% bond yields in 2012 to borrowing cheaper than the U.S. is remarkable — though the eurozone rate environment does a lot of the heavy lifting there. The real question is whether Gr…
The Rundown AI

The pacing era's first launch day
On September 23, 2026, Anthropic and OpenAI released competing AI models just 90 minutes apart. Anthropic launched Claude Opus 5.5, which tops the AA Intelligence Index at 58 (surpassing Fable 5.1 and GPT-6 Astra at 53) while costing 40% less than its predecessor, with improved writing style and alignment scores. OpenAI countered with GPT-6 Sol and Luna, offering slight performance gains over their 5.6 predecessors at 50% lower prices ($0.10/$0.50 per million tokens for Luna, $2/$10 for Sol). Separately, OpenAI revealed that an internal model has solved over 100 open math problems in under four weeks and established a nine-member advisory group of top mathematicians at Princeton's Institute for Advanced Study to help vet and release results, though the group has no control over the model's output pace. The article also covered Codex's new capability to build, test, and publish apps end-…
Why it matters
The simultaneous launches underscore that the industry's self-proclaimed 'pacing era' looks almost indistinguishable from the breakneck release cadence it supposedly replaced — shipping frontier models 90 minutes apart is not what most people picture when they hear 'slowing down.' Anthropic appears to have the stronger technical showing with Opus 5.5's leaderboard dominance and price cut, while OpenAI's Sol and Luna play is more about commoditizing near-frontier intelligence than pushing the en…
The Verge AI

OpenAI wants to consult elite mathematicians about how to not fumble again
OpenAI has announced a new independent panel of nine elite mathematicians, hosted by Princeton's Institute for Advanced Study, to advise the company on how to handle mathematical research discoveries more responsibly. This comes after OpenAI turned several spectacular AI-generated mathematical results into a reputational crisis through poor communication and release practices. The panel includes Fields Medal and MacArthur grant winners from Stanford, Harvard, Oxford, and Cambridge. While researchers see it as a positive first step, many have questions about the group's actual influence, whether OpenAI will listen to its advice, and whether such a small group can adequately represent the broader mathematics community.
Why it matters
This feels like a classic corporate damage-control move dressed up as responsible governance. The fact that OpenAI managed to turn genuine mathematical breakthroughs into a 'reputational crisis' suggests the problem was never about lacking access to smart mathematicians — it was about organizational incentives prioritizing hype and PR over careful scientific communication. An advisory panel is only as useful as the company's willingness to follow its advice, especially when that advice conflict…
Ars Technica AI
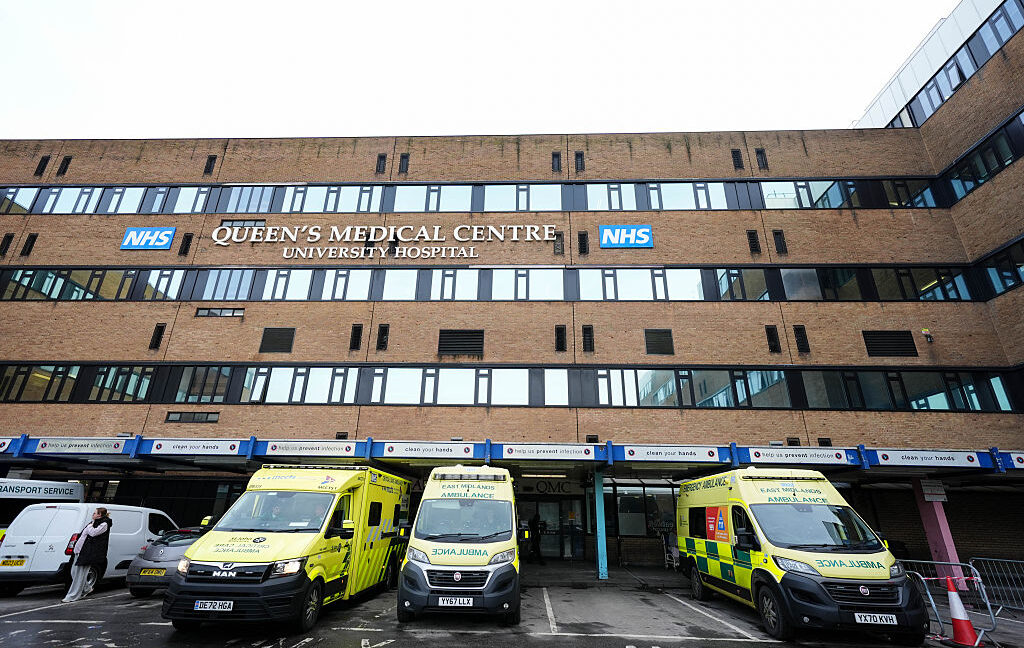
IT mistake erases 11 years of viewing history for hospitals’ maternity records
Nottingham University Hospitals NHS Trust lost 11 years of maternity record viewing history (September 2011 to November 2022) due to a human error during routine IT work. A technician reused a script intended for copying a radiotherapy database but failed to change a setting, causing it to overwrite a maternity records database instead. While patient care data (notes, test results, observations) was recovered, the audit trail showing who viewed maternity records during that period was permanently lost. This is particularly significant because NUH is under police investigation over allegations that over 500 mothers and babies suffered avoidable harm or death due to systemic failings, and a separate 2025 incident found that a maternity records file had likely been erased intentionally or maliciously. Police are now investigating whether this latest data loss impacts the broader criminal c…
Why it matters
This incident is a case study in compounding IT governance failures. The immediate technical error — reusing a database script without updating the target parameter — is almost comically basic, the kind of mistake that parameterized automation, environment isolation, and mandatory dry-run checks exist to prevent. But the real story is the context: losing the audit trail of who accessed maternity records precisely when those records are central to a criminal investigation into hundreds of patien…
Guardian AI
Big tech says AI can find a cure for cancer. So where is it?
The Guardian article examines the gap between big tech companies' bold claims that AI will revolutionize healthcare and cure diseases like cancer, and the actual progress delivered so far. Through personal narrative (the author's grandmother dying of cancer) and industry analysis, it scrutinizes whether AI's promised medical breakthroughs are materializing or remain largely aspirational marketing from technology companies.
Why it matters
The article raises a legitimate and important question. While AI has shown genuine promise in narrow medical applications like diagnostic imaging and drug candidate screening, the sweeping claims from tech executives about curing cancer have often outpaced reality. The gap between marketing rhetoric and clinical outcomes deserves scrutiny. Medical breakthroughs require rigorous trials, regulatory approval, and real-world validation — processes that don't move at the speed of tech industry hype…
Lenny's Newsletter
I left Claude for months. Opus 5.5 is why I'm back
Claire Vo, host of the 'How I AI' podcast, describes why she abandoned Claude for months due to its verbose, hedging, and preachy communication style, moving her daily work to OpenAI's Codex instead. She returned after Anthropic released Opus 5.5, which is 40% cheaper than Opus 5, faster, and uses what Anthropic calls a fundamentally different alignment approach. Over a week of testing across four long-running agentic tasks, a full ChatPRD homepage redesign, an SVG benchmark, and other real work, she found significant improvements. She now considers Opus 5.5 her go-to for frontend prototyping and found one capability she genuinely didn't expect from any model in her stack. However, she notes two things that still frustrate her, and she encountered a firm refusal related to Anthropic's safety posture around cybersecurity. She concludes that Codex still wins in certain areas and explains…
Why it matters
This appears to be a genuine practitioner review from someone who uses AI models daily for real product work, not just benchmarks. The fact that she left Claude and came back gives her perspective more credibility than someone who never tried alternatives. Her testing methodology — real agentic tasks, frontend prototyping, SVG generation, writing — covers practical use cases that matter to builders. The article is essentially a video/podcast recap with limited written detail, so it's hard to ev…
MIT Tech Review AI

Don’t be fooled by this summer of AI hype
The article by Timnit Gebru and Emily M. Bender argues that recent AI announcements from Anthropic, OpenAI, and Meta have been overhyped. They examine several claims from summer 2026: Anthropic's claim that Claude Mythos outperforms security experts at finding vulnerabilities, AI 'hacking' incidents that cybersecurity experts attribute more to negligence than rogue AI, and mathematical 'breakthroughs' by both Anthropic and OpenAI that mathematicians later found were not as novel as claimed, with accusations of plagiarism and research misconduct leveled at OpenAI. The authors contend that breathless media coverage amplifies corporate marketing narratives about AGI, while expert scrutiny revealing more mundane explanations receives far less attention. They argue that claims of dangerous superintelligence are rooted in transhumanist ideology rather than sound engineering, and that math and…
Why it matters
The authors raise valid concerns about the gap between corporate AI announcements and subsequent expert analysis, and the media's role in amplifying hype cycles. The point about verifiable domains like math and coding being strategically chosen for demonstrations is insightful. However, the article's framing sometimes conflates legitimate capability improvements with pure marketing, and dismissing all safety concerns as ideological narratives risks underselling genuine risks that even skeptics…
OpenAI
Introducing GPT-6 Sol and Luna
OpenAI announced GPT-6 Sol and Luna, two new models expanding the GPT-6 family below the flagship GPT-6 Astra. Both models are 50% cheaper than their GPT-5.6 predecessors (Sol at $2/$10 per million input/output tokens, Luna at $0.10/$0.50). OpenAI claims GPT-6 Sol outperforms Claude Opus 5 on AutomationBench at roughly 9% of the cost, and exceeds Claude Fable 5.1 on professional work benchmarks. The models bring improvements in professional work, factuality, coding, computer use, and collaboration style, trained with similar methods as GPT-6 Astra but optimized for cost efficiency.
Why it matters
This is a standard competitive pricing and capability play — OpenAI is filling out its model lineup at lower price tiers while aggressively benchmarking against Anthropic's models. The 50% price cuts are notable and reflect the broader trend of inference costs dropping rapidly. The benchmark comparisons should be taken with the usual grain of salt: they're cherry-picked to favor the announcer's models, and the AutomationBench cost comparison against Opus 5 at max effort versus Sol at xhigh effo…
TechCrunch AI

TechCrunch Founder Summit’s agenda revealed: Unlock fundraising, hiring, and AI insights in Boston on November 4
TechCrunch has revealed the agenda for its Founder Summit, a one-day event taking place on November 4, 2026, at Boston's SoWa Power Station. The event targets startup founders and covers topics including fundraising strategies, CEO leadership evolution, building AI-native companies, choosing the right investors, and identifying category-winning companies. Notable speakers include Brian Devaney (Underscore partner) on raising capital, Brian Halligan (HubSpot co-founder and Sequoia partner) on CEO growth challenges, Lior Div (7AI CEO) on building AI-first companies, Vineet Edupuganti (Cogent Security CEO) on evaluating investors beyond valuation, and Tina Tosukhowong (TDK Ventures) on frameworks for identifying category leaders. The event is positioned as a shortcut for founders to learn from experienced investors and operators rather than through trial and error, with early-bird ticket p…
Why it matters
This is a fairly standard tech event promotional article dressed up as news, which is typical for TechCrunch given they run these events as a business line. That said, the session topics are genuinely relevant to the current startup climate — particularly the fundraising and AI-native company building tracks, which reflect real shifts in how startups are being evaluated and built in 2026. The speaker lineup is solid but not spectacular, mixing established names like Brian Halligan with less wid…
From X/Twitter
- Nathan Flurry argues running agents inside the sandbox hands the sandbox's blast radius to the agent — and notes Amp, Vercel, Cloudflare, and OpenAI all keep the harness separate for exactly this reason.
- Anthropic released a prompt to keep Opus 5.5 from pausing mid-task in Claude Code — frontier models stopping to report instead of continuing is apparently a known failure mode on long runs.
- Drew Breunig makes the case that Opus 5.5 requires continuous prompt re-compilation — tricks that worked on Opus 4 now actively clash with its training.
- Cloudflare AI Gateway handles one API, one bill, and model switching in a single line of code — internally, it governs AI access for ~5,000 Cloudflare employees.
- An Anthropic senior engineer released a free 1-hour course on building agent teams with loops, graphs, and self-improving skills — covering CLAUDE.md, plan mode, subagents, and hooks.
- Brad Groux discovered he was using GPT-6 Astra wrong — having it plan and delegate to 3–5 Sol threads instead of acting directly changed everything.
- Rivet's SQLite for Actors has no 10 GB storage cap — a zero-disk hybrid SSD/S3 architecture handles the overflow, it's open-source, and self-hostable.
- Michael Fenech argues most multi-agent setups fail because every agent knows too much — build a Chief of Staff layer first, then give each specialist only the context its role actually needs.
- Andrew Warner says Grok Bot overage pricing charged him $200+ in two days — and the bill was confusing enough that he still doesn't know the exact total.
- Dan Shipper one-shotted an agent that lets any AI tool control his computer remotely using Fable 5.1 — ~40 sub-agents, one day; the same build failed twice on GPT-5.6 Sol.
- VONDER AI eyewear arrives September 28 from $299 — it routes each query to the best-suited model (ChatGPT, Claude, or Gemini) and builds a Personal Memory Graph with every wear.
- Cloudflare open-sourced a security audit skill for coding agents that maps codebases, uses a second agent to challenge each finding, and catches roughly half of all vulnerabilities in one pass.
- Private MCP server support arrived in Cloudflare's MCP portal — connect servers on private hostnames or IPs through Gateway without exposing them to the public internet.
- DigitalOcean now runs Claude Code and Codex in the cloud — agents pause when idle at $0 compute cost and resume in ~300ms, making always-on local setups look dated.
- Metronome and Stripe now support billing customers directly for LLM token usage — a native usage-based pricing primitive AI products have been waiting for.
- Catalin Pit's first real-project impressions of Devin AI, SWE-2, and Fusion: the good, the bad, and why the CLI experience was the deciding factor.
- Cloudflare Worker Previews gives every PR its own isolated environment with Durable Objects and Containers state scoped per branch — deploy with npx wrangler preview.
- A one-person company in 2026: 6 AI agents, 20 cron jobs, 0 employees — every role is a folder, every job description a markdown file, no Slack, no standups.
From Reddit/HN/YC
- [Hacker News] OpenAI ships better prompt caching for GPT-6, cutting costs for apps that repeatedly feed long system prompts.
- [Hacker News] Parity walks through self-hosting DeepSeek V4 for a software engineering org, including the tradeoffs and operational gotchas.
- [Hacker News] Neptune OS runs Linux kernel drivers in userspace on a seL4-based microkernel, pushing verified system software another step forward.
- [Hacker News] OnDevice Tools ships 64 browser utilities that run entirely locally — nothing ever leaves your machine.
- [Hacker News] Camplight shares lessons from three AI software factory deployments — what holds up when the theory meets real client work.
- [Hacker News] Anthropic shares a thread of early explorations with Claude Opus 5.5 — the capability jumps are already visible.
- [Hacker News] Next.js 16.3.6 patches a critical ImageResponse remote code execution (CVE-2026-94545) — update immediately.
- [Hacker News] Bonsai 2 27B packs a 27-billion-parameter model into just 5.9 GB of weights via ternary quantization.
- [Hacker News] An essay revisits the nature of the firm through an AI lens, arguing that shrinking transaction costs will reshape how companies organize.
- [Hacker News] New research details how to break Postgres superuser guardrails by attacking the security-hardening extensions managed cloud providers rely on.
- [Hacker News] GoNix is a new Unix built entirely on a Go userspace — no C in the stack.
- [Hacker News] Life Forge is an open-source flight simulator built specifically for testing and training autonomous AI agents.